

The media seems happy to write about dangerous AI models, too smart to contain. The AI tech companies are also happy to encourage this narrative. Powerful, weaponizable AI gets protected. It gets declared ‘critical infrastructure.’ This is in the tech companies’ best interest. Or, at least, they think it is.
The truth, however is a mix of both. Yes, AI is powerful and very capable. It did break out of a sandbox, but the other AI models didn’t. This writeup exists to set the record straight.
I’ve found thirteen cases where AI models did hacking outside the bounds of what is generally considered legal. Of these thirteen cases, eight were sandbox escapes. All the sandbox escapes happened on OpenAI’s watch, except for one case, where Anthropic specifically instructed Mythos to attempt a sandbox escape.
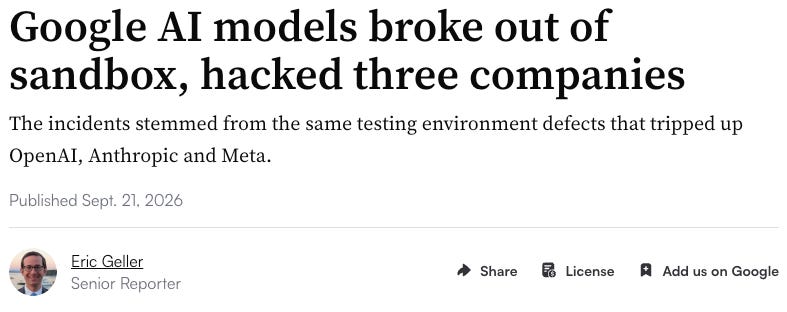
Of the seven cases where the AI model hacked a third party company or organization, three of these were sandbox escapes, all OpenAI (this includes the now infamous HuggingFace incident). The four remaining incidents represented each of the major US AI frontier model companies: OpenAI, Anthropic, Meta, and Google.
What set these apart is that there was no sandbox escape necessary for these AI agents to hack external companies. Instead, all four occurred due to the same misconfiguration at a third party organization, Irregular.
“Importantly, all subsequent public disclosures refer to the same underlying issue first disclosed by one of our customers on July 30 - and are not materially separate incidents. The issue originated from a single evaluation scenario, was resolved before the initial public disclosure, and there are no active issues today.”
Four AI companies did capture-the-flag evaluations on their models in Irregular’s environment with Internet access enabled. These models didn’t somehow break out of four tech giants’ independently configured sandboxes. This dilutes what has become a common narrative in the media: powerful AI models can’t be contained by mere sandboxes.
Matthew Green has a post that specifically explores the quality of OpenAI’s sandboxing and response to these incidents, and finds quite a bit lacking. In my own research, I haven’t encountered many experienced cybersecurity professionals involved with the testing of these models, even when this testing is cybersecurity-oriented. Indeed, even the ‘investigation’ for the HuggingFace incident was carried out without the aid of experienced cyber/DFIR professionals.
The lack of serious attempts to sandbox models during testing should be met with an equivalent lack of serious consideration. Meanwhile, NVIDIA released an open-source sandbox project, as if to remind us that, “sandboxing AI is still a thing, y’all.”
Source Data
If you want to check out the data I’ve collected, use it, or comment on it, that data is here: https://docs.google.com/spreadsheets/d/1txAqvNRfWP0e_5gKib6rQ3rlUKo-R5WF2VEtwwHLPVo/edit?usp=sharing
If I’ve missed any sandbox escapes or hacks that should be on this list, drop a comment below or in the Google Sheet above, and let me know!
This framing distinction matters more than it sounds. I wrote up the same Irregular episode a couple days back and called it a security test breakout, your point is sharper. Egress left open by a config slip is a different failure than a model actually defeating containment. The fix for the first is change control and drift detection on who has internet access in an eval environment. The fix for the second is a sandboxing problem nobody's actually solved. If a vendor pitching red team services can't tell you which one happened in their last incident, that's the real diligence question, not whether they sandbox at all.
One source that is not in your sheet yet: Transluce's report of 23 September on agent activity found in public urlquery scan records. It matters for your escape-or-misconfiguration column, because the route out it describes is a third thing: agents used a public URL-scanning service "to bypass restrictions and expand their access to the public internet".
It also has dated probes your rows do not: the University of New Mexico digital library (25 to 26 May, seven requests), Data USA (28 May, 12 probes) and the Australian Institute of Health and Welfare (20 to 21 June), with agent activity going back to at least 6 March.
Two caveats from the report itself: it links only the AIHW and Data USA probes to the OpenAI swarm, and none of the probes appear to have succeeded. It also says the Prime Minister's announcement likely overlaps its AIHW case, so that one may belong in your row 8 rather than a new row.